How Bot Traffic Created 347k Junk Rows in PostgreSQL
A Query That Took 1.3 Seconds
A GraphQL request on our Reviews app was spending 1,320 ms in a single query. Not the whole request — one query, for one merchant, counting completed reviews grouped by source and channel. The kind of thing that should take a few milliseconds.
The reviews table behind it was big: about 7 million rows, a 6 GB heap, and 1.1 GB spread across 13 indexes. All of them single-column or expression indexes. Nothing composite, nothing partial. My first thought was the obvious one — this query needs an index that matches how it filters and groups. I figured I’d run EXPLAIN (ANALYZE, BUFFERS), confirm the plan was doing something dumb, and add a composite index.
40,453 Reviews, only 12 Completed
EXPLAIN (ANALYZE, BUFFERS) told a different story straight away. This merchant had 40,453 reviews, and exactly 12 of them were completed. Postgres was walking roughly 200 MB of scattered heap pages — 26,015 heap blocks — to throw away 40,441 rows and hand back a dozen.
Timing was all over the place on the identical query: 263 ms, 795 ms, 1,320 ms. That’s the signature of random I/O living or dying on page-cache luck, not a bad plan shape. A better index could speed up the query, but it wouldn’t explain why one merchant had over 40,000 incomplete reviews in the first place.
So the question changed. Not “which index,” but “why does one merchant have 40k incomplete reviews and 12 completions?”
Where Were These Reviews Coming From?
It wasn’t one merchant. It was a live incident, and the incident was bots.
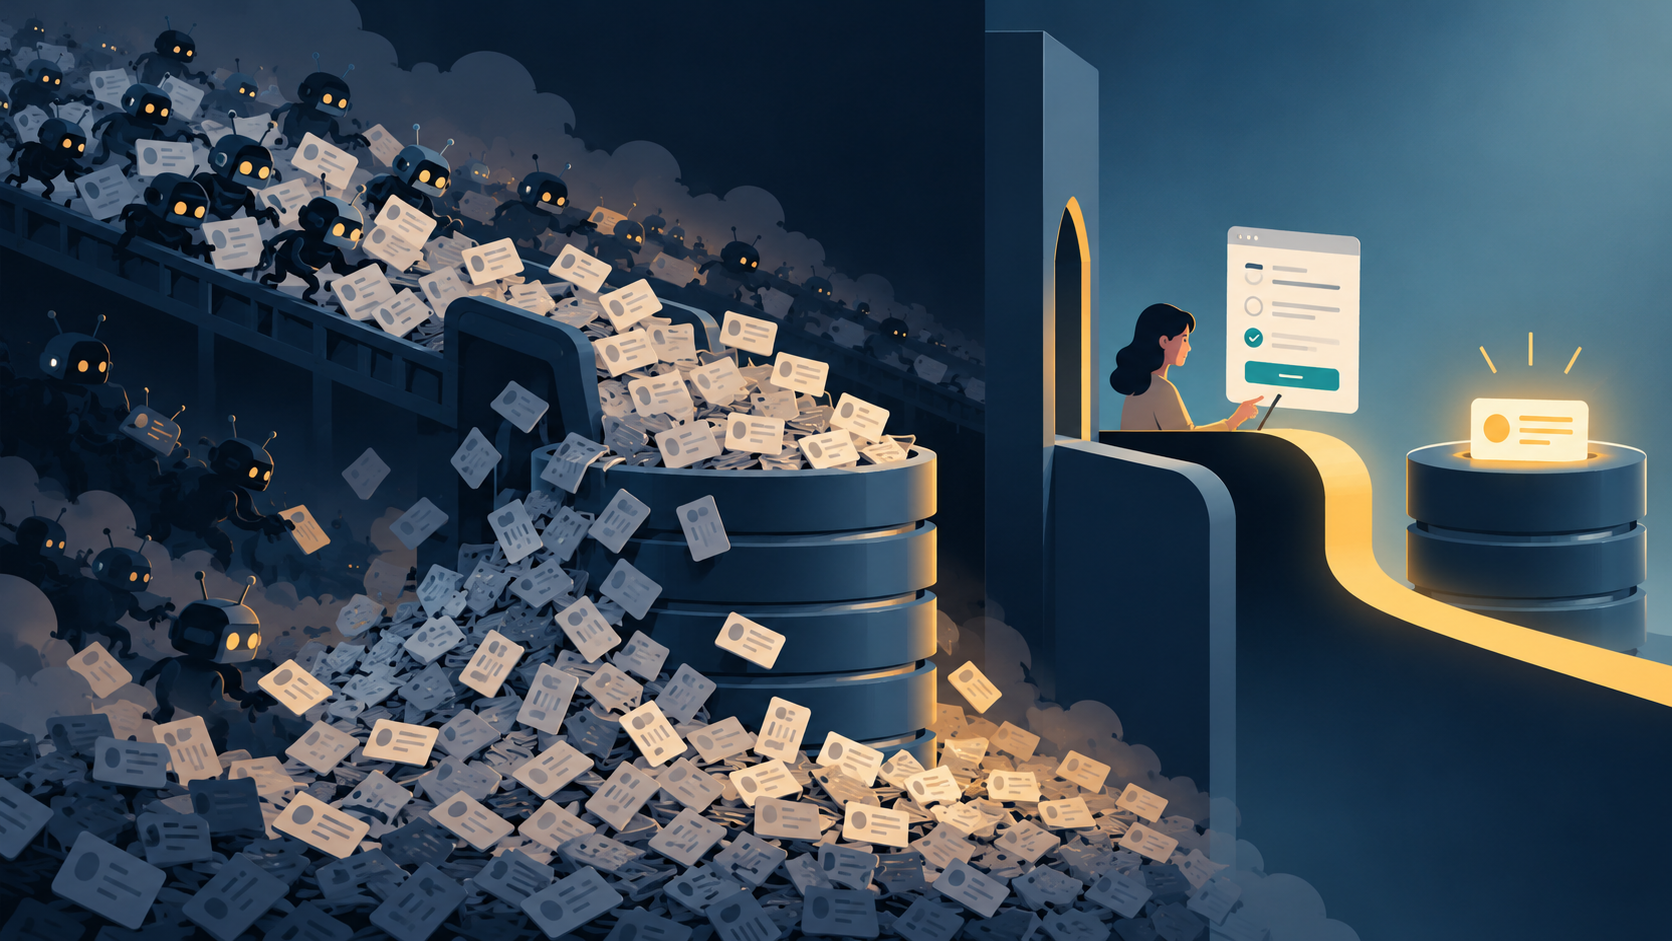
Our short survey links are public URLs by design — they go on receipts, in text messages, on QR codes. Starting in September 2026, something started hitting them at roughly 10x normal traffic. Some of it looked like ordinary crawlers and link scanners walking anything that resolves. Some of it looked targeted: the same short links, over and over. Either way, the route serving those links persisted a review row before redirecting to the survey form. A GET request that writes to the database. Every bot hit minted a new incomplete review whether or not a human ever saw the form.
That one design decision turned a traffic spike into a data spike: 30k–49k incomplete rows a day, across roughly 24k merchants, none of them ever going to be completed.
This is where my understanding of the problem flipped. Junk rows aren’t inert. They inflate the table, get scanned by every query that can’t skip them, and bloat every index. The slow query was a symptom. The disease was that we were writing data nobody asked for.
The Cleanup Job Was Losing
There was already a nightly job for exactly this situation: delete incomplete reviews older than a day, capped at 25k deletions a night. Before the bots it handled a few hundred rows and never came near the cap. Now it was being handed on the order of 50k new rows a day.
It didn’t crash. It just couldn’t keep up. 50k in, 25k out, and the gap compounds — that’s how the backlog climbed to 347k rows while every nightly run reported success.
The tempting move was to crank the cap to 50k or more. I didn’t like it. That would double the nightly delete load on a table already absorbing 50k unwanted inserts a day. Every one of those rows was work the database should never have done once, and raising the cap asks it to do that work twice. It’s a bandaid that hands the database more load, not less.
Deleting 250k Rows Wasn’t Enough
The backlog still had to go, so I started with the ten worst-hit merchants, including the one from the original query and its 40k junk rows. Those ten accounted for about 70% of the junk — almost 250k of the 347k rows. Clearing them cut the backlog by more than two thirds and bought time to do the long-term fix properly instead of under a production alert.
What it didn’t do was make the query fast. I re-ran the original query expecting a big drop and got 1,070 ms and the same 26,015 heap blocks. The rows were gone; the cost of scanning past them wasn’t.
DELETE only marks tuples dead. The heap pages and index entries stick around until VACUUM runs, and autovacuum wasn’t going to trigger on its own — the dead-tuple count sat well under the threshold a table this size requires. I ruled out VACUUM FULL quickly: a bloat estimate showed nothing meaningful to reclaim, so it would have rewritten the entire 6 GB table under an exclusive lock for nothing. Plain VACUUM (ANALYZE) was the right tool.
Even that had to be wrangled. The first attempt died with an out-of-memory error, and so did the second. The Postgres version we run pre-allocates its entire dead-tuple tracking array up front, sized from maintenance_work_mem, regardless of how many dead tuples exist. It was asking the host for 410 MB to track roughly 1.5 MB of actual work — a quarter-million dead tuples at six bytes apiece. Lowering that setting for the session let it finish in a single pass.
The Fix Wasn’t Another Index
At this point the database-side answer was sitting right there: a partial index whose predicate excludes the junk structurally. A composite index on the grouping columns, restricted to completed, non-deleted reviews, built concurrently so it doesn’t lock the table. Junk rows could never enter it, so the query’s cost would track the data we care about instead of the data we’d accumulated.
But step back and look at what that index actually is. It’s a bandaid over a table that shouldn’t have the junk in it at all. It makes one query shape immune. The rows still get written on every crawler hit, still bloat the heap and the other 13 indexes, still have to be deleted by a nightly job that had already proven it couldn’t keep up. And once the junk stops arriving, the index exists to defend against a problem that no longer occurs — you add it under pressure, then have to remember to remove it later.
So the fix we shipped was to change when a review gets created. A page view on a short survey link no longer persists anything. A review row only comes into existence when a human actually engages with the survey. Crawlers hit the redirect, follow it, and leave nothing behind.
That one change cuts off every downstream symptom at the source. Every bot hit had been an INSERT, then a nightly DELETE, then a dead tuple for vacuum to chase. Not creating the row eliminates the write, the delete, and the vacuum work in one move, and the cleanup job should go back to the few hundred rows a night it was built for. We could have shipped the bandaids and they would have worked. Fixing creation instead meant less total work for the database and no index we’d only have to take out again.
What I’d Do Differently
The broader lesson I’m taking from this: sometimes the right optimization isn’t making work faster, it’s noticing that the work shouldn’t exist. I spent the first part of this investigation trying to make Postgres better at skipping junk. The answer was to stop making junk.
What’s Next
- Confirm the backlog drains to zero and the original query settles on its own once the junk is gone and vacuumed. If it doesn’t, the partial index is the next lever — and this time it would be a permanent design choice rather than a patch over an incident.
- Alert when the nightly cleanup job hits its cap. A job that deletes exactly its limit every night is a job that’s losing ground, and this one lost ground for weeks because “ran successfully, deleted 25k” looks healthy on every dashboard.